Qwen4-Max: Price, Specs and How to Use It in Claude Code (Nov 2026)
Qwen4-Max is Qwen's new 2.4T flagship with a 1M context: API price, specs, Token Plan, and setup in Claude Code and Qwen Code, checked 16 Nov 2026.
Qwen4-Max is the new flagship model from Alibaba’s Qwen team, released on 16 Nov 2026 with a 1M token context window, native vision and an API price of $1.50 per million input tokens and $4.50 per million output tokens. You can use it inside Claude Code and Qwen Code today. Checked 16 Nov 2026.
For a team of agents on your own work, Munder Difflin is free and open source: a desktop app that runs a team of AI agents for all kinds of knowledge work, coding included, on your own computer. This page sticks to what Qwen and QwenCloud publish.
What is Qwen4-Max?
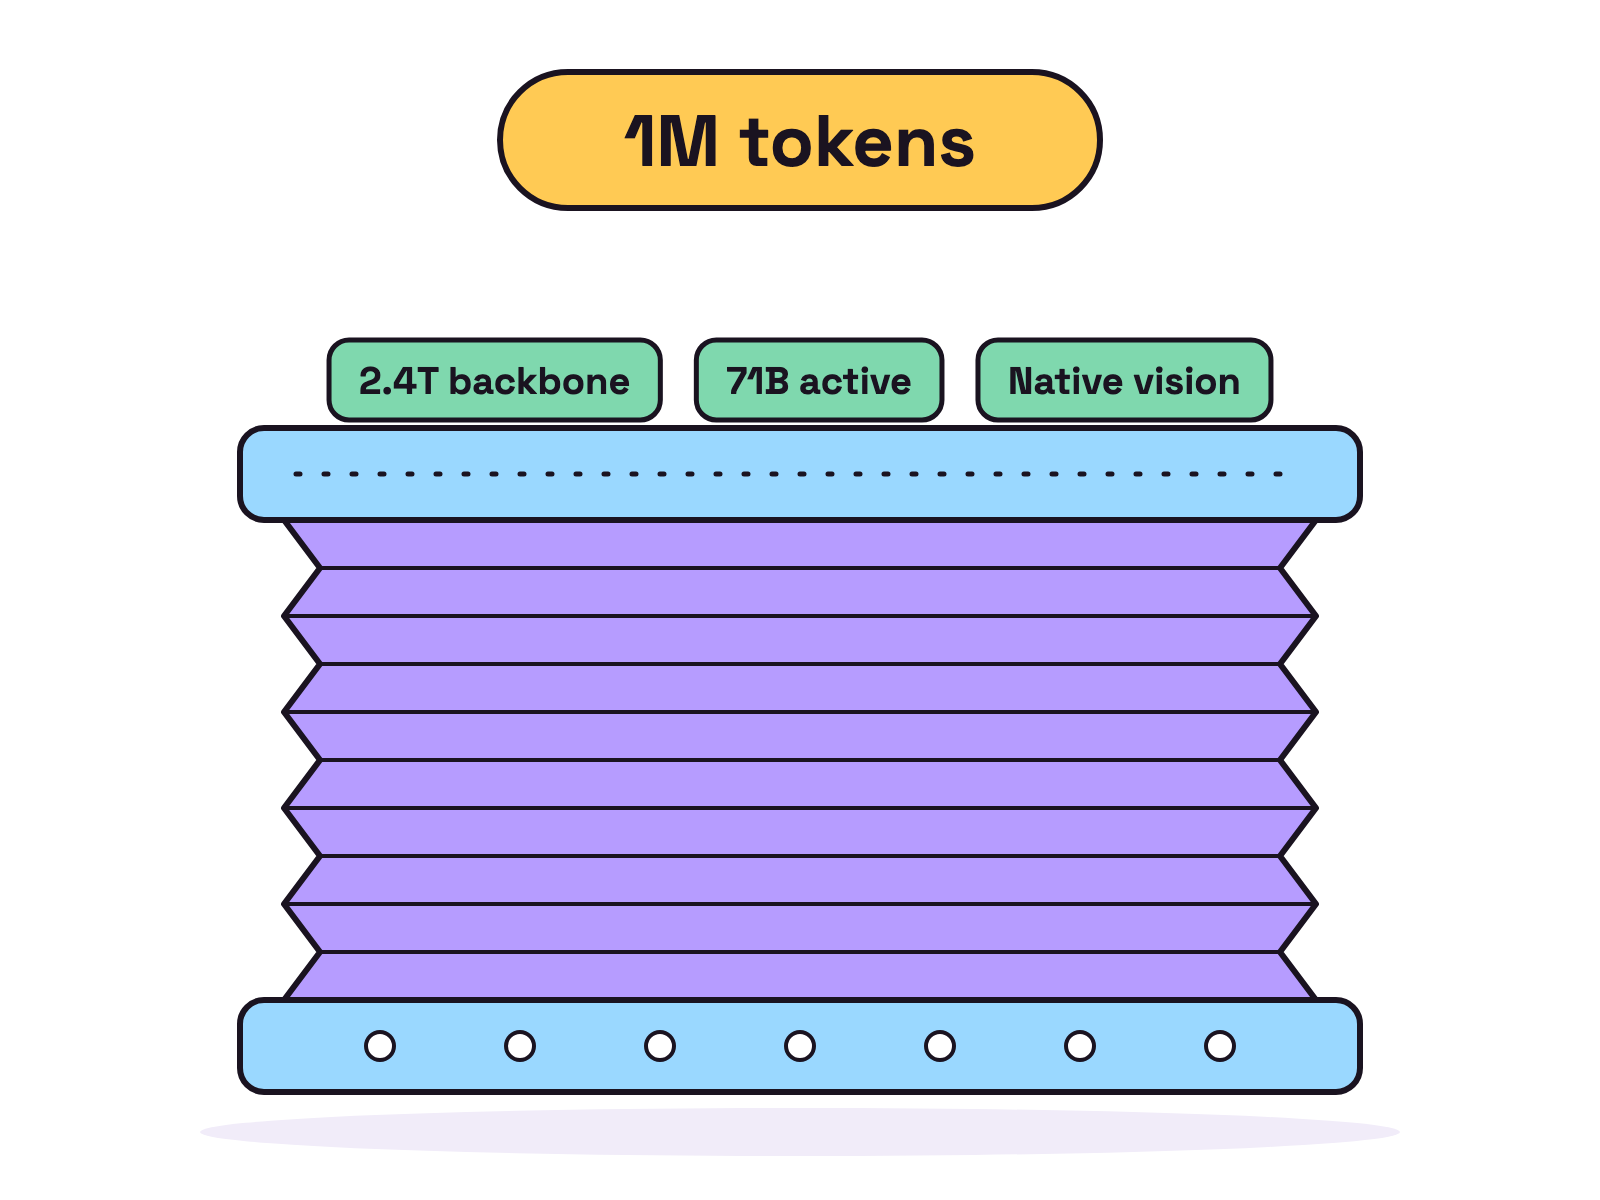
The first model on Qwen’s new Qwen4 architecture. Qwen’s launch post, dated 16 Nov 2026, calls it “your new AI teammate for work, creativity, and discovery” and gives these numbers:
- 2.4T backbone parameters, with 71B activated per token, plus 328B N-gram Embedding parameters.
- A 1M token context window and native vision.
- A sparse mixture of experts design that pairs Gated DeltaNet layers with Qwen Sparse Attention, which picks relevant context in small blocks to cut the cost of long inputs.
The post names 3D modeling in Blender, game development in Unity, Unreal Engine and Godot, finance, law, healthcare and science as target work. It also describes “24/7 agents” that work through long tasks in stages “while keeping users in control.”
What does Qwen4-Max cost?
$1.50 per million input tokens and $4.50 per million output tokens through the API, as of 16 Nov 2026. The QwenCloud model page, read on 16 Nov 2026 for the Singapore region, lists:
| Item | Price per 1M tokens, 16 Nov 2026 |
|---|---|
| Input | $1.50 |
| Output | $4.50 |
| Input from implicit cache | $0.075 |
| Explicit cache, 5 minute creation | $1.875 |
| Explicit cache, 1 hour creation | $3 |
| Explicit cache read | $0.075 |
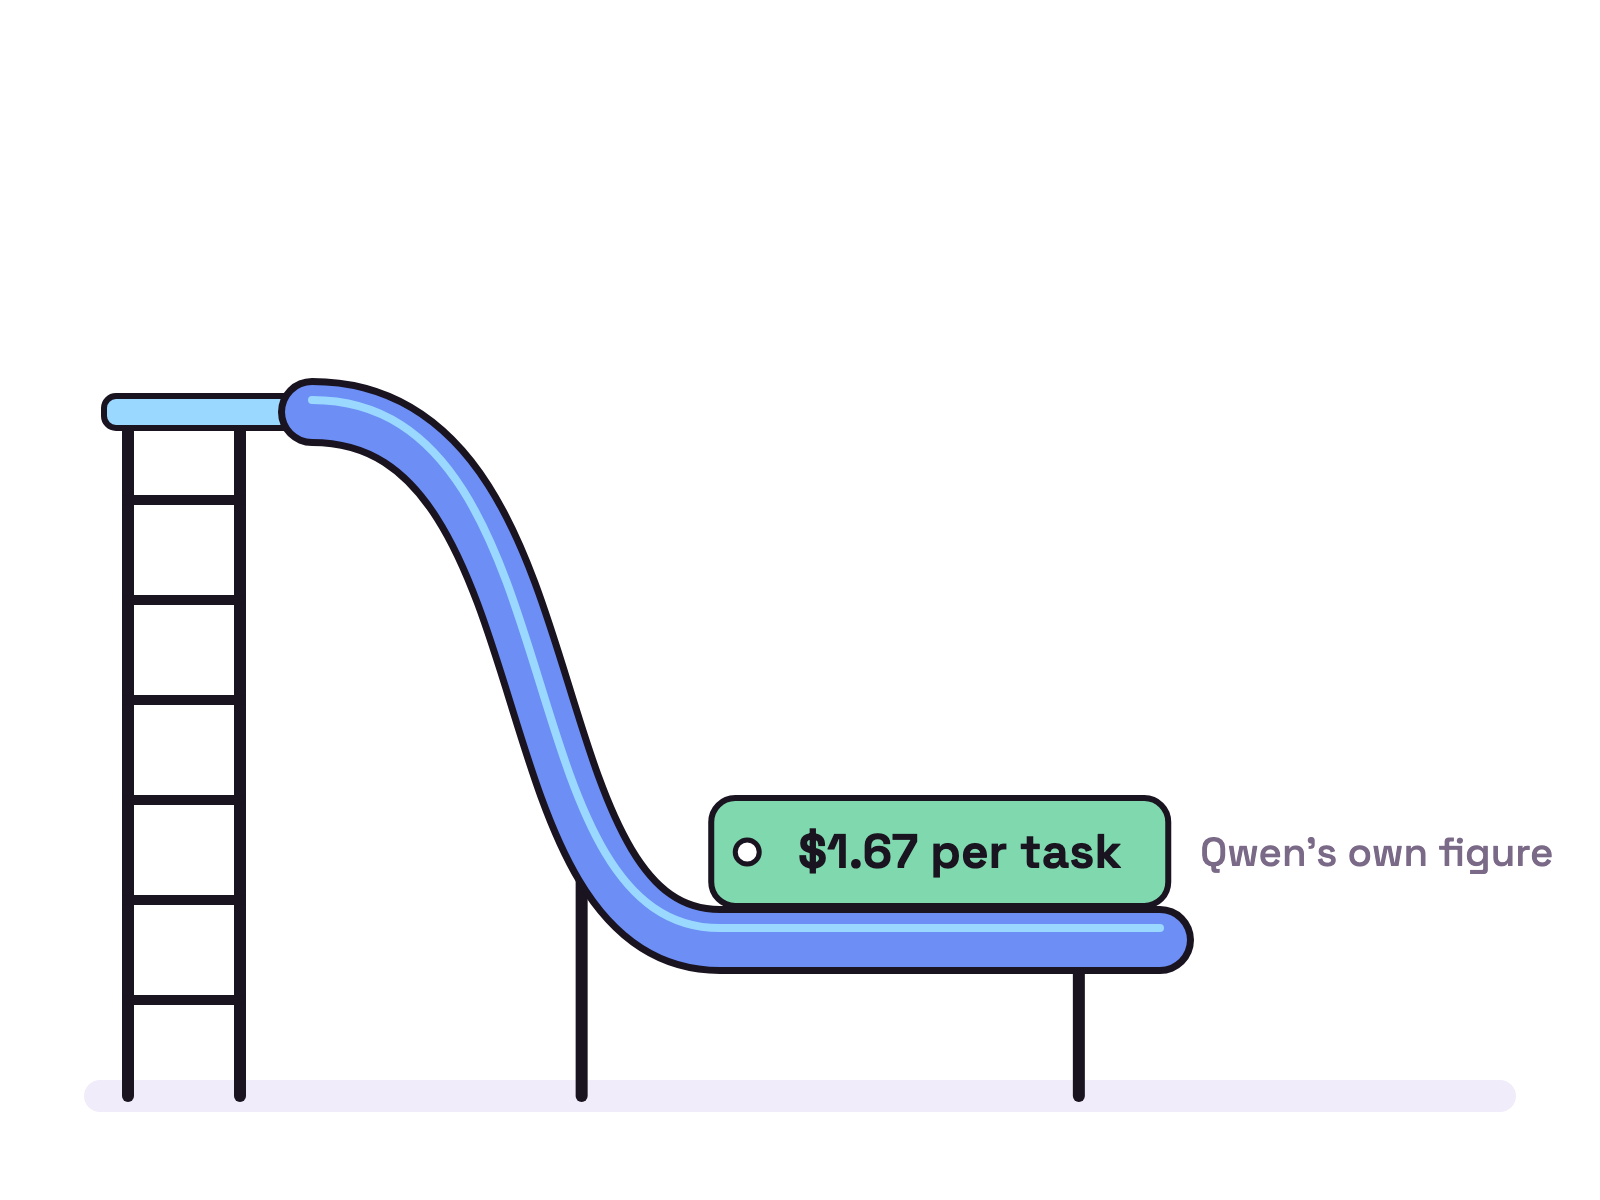
Qwen’s post says it has “lowered API prices compared with Qwen3.8-Max, with particularly large reductions in cached-input pricing.” Its own figure for a task on its Work360 test: the average cost “drops from $4.43 to $1.67”, which it calls a 62% reduction. That is Qwen’s measurement.
The other route is the Token Plan, a subscription “billed in Credits” that QwenCloud says works across tools “such as Claude Code, Cursor, Qwen Code, Codex, Qoder, and OpenClaw”. Individual plans come in four tiers: Lite, Essential, Standard and Pro. Its updates page lists Qwen4-Max on both Individual and Team Edition from 16 Nov 2026.
How good is Qwen4-Max?
On Qwen’s own numbers, clearly better than the last Max. Qwen built Work360, a benchmark that covers 26 domains, 182 subdomains and 721 specialised fields. Qwen4-Max scored 52.69 there, against 47.74 for Qwen3.8-Max. The 16 Nov 2026 post also says it uses fewer tokens: about 24% and 35% fewer on Work360 at Xhigh and High effort, and about 48% and 49% fewer on Terminal-Bench 4.0.
Our view: these are vendor results, and Work360 is a benchmark the vendor designed. Compare it on your own tasks before you move a team over.
How do you use Qwen4-Max in Claude Code?
Point Claude Code at QwenCloud’s Anthropic compatible endpoint. The model page says Qwen4-Max is compatible “with the OpenAI and Anthropic APIs”. QwenCloud’s Claude Code guide, read on 16 Nov 2026, says to set ANTHROPIC_DEFAULT_OPUS_MODEL to qwen4-max and keep CLAUDE_CODE_MAX_CONTEXT_TOKENS at 983616. With a Token Plan key, the core lines are:
export ANTHROPIC_AUTH_TOKEN="YOUR_API_KEY"
export ANTHROPIC_BASE_URL="https://token-plan.maas.qwencloudapi.com/apps/anthropic"
export ANTHROPIC_DEFAULT_OPUS_MODEL="qwen4-max"
export CLAUDE_CODE_MAX_CONTEXT_TOKENS="983616"
The guide’s full block also sets the main, Haiku, Sonnet and subagent models. With a pay as you go QwenCloud key, the base URL for Singapore is https://ap-southeast-1.maas.qwencloudapi.com/apps/anthropic, and keys only work in the region where you made them. If long answers are cut off, the guide says to set CLAUDE_CODE_MAX_OUTPUT_TOKENS=131072. Check the setup with claude -p "Hello".
How do you use Qwen4-Max in Qwen Code?
Run qwen, pick Alibaba ModelStudio and a billing plan, choose Singapore and paste a Token Plan or QwenCloud API key, per QwenCloud’s Qwen Code guide, read on 16 Nov 2026. Check it with qwen -p "Hello". The default output limit for qwen4-max there is 32768 tokens; for longer output, the guide says to set generationConfig.samplingParams.max_tokens in the model entry. Qwen’s post also names QwenWork, Qoder and QwenStudio as places to use the model.
What is Live Delivery?
A way for long agent runs to hand over work in stages. Qwen’s post says the agent “delivers a usable first version early” and takes guidance while it runs, so mistakes show up before the end. Qwen is “open-sourcing the Qwen-Live-Delivery-Plugin”: the GitHub repository was created on 14 Nov 2026 under the Apache 2.0 licence.
Where does a team of agents fit?
Qwen pitches Qwen4-Max for long tasks that keep going while you do other work. We think that pairs best with a setup where each agent owns one job and a person approves what ships. In Munder Difflin, agents run on engines such as Claude Code, Codex and Gemini CLI and use MCP servers and skills. If you are new to it, start with the install guide. For other recent model launches, see Kimi K3.1 Pro and DeepSeek V4.1 Flash, and for tools that run several agents at once, see Herdr alternatives.
Qwen4-Max at a glance, checked 16 Nov 2026
| Spec | Qwen4-Max |
|---|---|
| Model ID | qwen4-max |
| Released | 16 Nov 2026 |
| Backbone | 2.4T parameters, 71B active |
| Context window | 1M tokens |
| Maximum input | 991K tokens (model page) |
| Maximum output | 131,072 non thinking, 262,144 thinking plus answer (tool guides); model page lists 393K |
| Input | Text, images and video |
| Price as of 16 Nov 2026 | $1.50 input, $4.50 output per 1M tokens |
| Where | QwenCloud API and Token Plan, QwenWork, Qoder, QwenStudio |
FAQ
How much does Qwen4-Max cost?
$1.50 per million input tokens and $4.50 per million output tokens on its QwenCloud model page for the Singapore region, read on 16 Nov 2026. Input read from the cache is $0.075 per million tokens. Token Plan subscribers pay in Credits instead.
Is Qwen4-Max open source?
Qwen's launch post names no weights download. It says the model is available on QwenCloud through the Token Plan or the API, and on QwenWork, Qoder and QwenStudio. Qwen is open sourcing the Qwen-Live-Delivery-Plugin, an Apache 2.0 repository on GitHub, and says smaller models in the Qwen4 family are coming to open source.
Can I use Qwen4-Max in Claude Code?
Yes. QwenCloud's Claude Code guide, read 16 Nov 2026, points ANTHROPIC_BASE_URL at QwenCloud's Anthropic compatible endpoint, sets ANTHROPIC_DEFAULT_OPUS_MODEL to qwen4-max and keeps CLAUDE_CODE_MAX_CONTEXT_TOKENS at 983616.
What is the Qwen4-Max context window?
1M tokens, per Qwen's launch post and the QwenCloud model page. QwenCloud's tool guides give a maximum output of 131,072 tokens in non thinking mode and 262,144 tokens for thinking and the final answer combined. The model page itself lists 393K Max Output.
What happens to qwen4-max-preview?
QwenCloud's Token Plan Individual page says the preview runs from 10:00 on 11 Nov to 24:00 on 25 Nov 2026 (UTC+8) and that the preview model will be retired after the preview ends. Qwen4-Max itself became available on Token Plan on 16 Nov 2026.