Claude Code Router: What It Is, How It Works and How to Install It
Claude Code Router, checked 14 Oct 2026: what the local gateway does, how to install it, which providers it lists, and what Anthropic says about it.
Concepts
Read →
Tag
25 posts tagged Cost.
Claude Code Router, checked 14 Oct 2026: what the local gateway does, how to install it, which providers it lists, and what Anthropic says about it.
Muse Code vs Claude Code, checked 14 Oct 2026: the main plans and monthly prices, the models each runs, where each installs, and which one to pick.
Gemini 4 Argon pricing, checked 13 Oct 2026: $2 input and $10 output per 1M tokens through 30 Nov, then $4 and $20. No free tier. Worked examples inside.
Codex usage limits vs Claude Code usage limits, checked 10 Oct 2026: the five hour window, weekly limits, credits and how to check usage on each plan.
Seven Cursor alternatives checked on 8 Oct 2026: Claude Code, Codex, Cline, OpenCode, Zed, Devin Desktop and GitHub Copilot, by licence and price.
Codex vs Cursor, checked 7 Oct 2026: what each is, licence, paid plans from $8 a month, models, where each runs, and whether Codex works inside Cursor.
Claude Cowork does office work, Claude Code writes software. What each is, where it runs, which plans include it and what it can touch, checked 6 Oct 2026.
OpenCode vs Claude Code, checked 6 Oct 2026: licence, price to start, models, where each runs, and whether a Claude subscription works in OpenCode.
Seven Claude Code alternatives checked on 5 Oct 2026: Codex CLI, OpenCode, Cursor, Gemini CLI, Cline, Pi and Aider, by licence, starting price and models.
Codex pricing checked 5 Oct 2026: which ChatGPT plans include Codex, US prices from $0 to $500, how usage limits are counted, credits and API key rates.
Aider vs Claude Code, checked 15 Sep 2026: how each edits code, which models it runs, what it costs, MCP, and Aider's stalled releases.
Stretch a Claude Code Max plan: model choice, context hygiene, prompt caching, subagents and unattended runs, checked against Anthropic's own pages.
Claude Code vs Google Antigravity, checked 14 Sep 2026: terminal agent or desktop agent app, Claude inside Antigravity, plans, limits and a verdict.
Claude Code vs Cursor, checked 29 Sep 2026: a dated table of models, plans, background agents, MCP and licences, then when to pick each or run both.
There is no Codex Max plan. What ChatGPT Pro 5x and 20x give you in Codex, how the weekly limit works, and how to stretch it.
Is the Claude Max plan worth it? Max 5x and 20x against Pro, checked 29 Sep 2026: price, five hour and weekly limits, Fable, and the API break even.
Claude Code pricing checked 29 Sep 2026: Pro, Max, Team, Enterprise and API rates, usage limits, what changed this year, and whether Claude Code is free.
Our own floor was under reporting what it cost by 59 percent. The counter was cumulative since process start, the app restarts, and the session id stayed the same. Here is how a monotonic invariant let us recover the real number from an append-only log.
A guide to Munder Difflin's Command Center in 0.5.2: the kanban with task dependencies, the ask me tab, triggers, memory, live token use against each agent's budget, and when to watch the board instead of the floor.
A practical guide to mixing agent engines on one Munder Difflin floor: Claude Code as orchestrator, Codex for coding bursts, Copilot for dispatched tasks, and OpenCode/Crush/pi.dev for BYOK keys and local models.
Spinning up tens of identical top-tier CLI agents feels powerful and burns tokens on work a cheaper agent could do. A mixed-capability swarm with shared memory wins on cost — and often on quality.
CLI agents are powerful because they have terminal-level access: they run builds, tests, and git, and verify their own work by executing it. Here's why that matters — and the concrete ways Munder Difflin cuts token consumption while doing it.
Caching, batching, model tiering, context discipline, local-first — the five levers that cut a multi-agent fleet's bill, and how they compound.
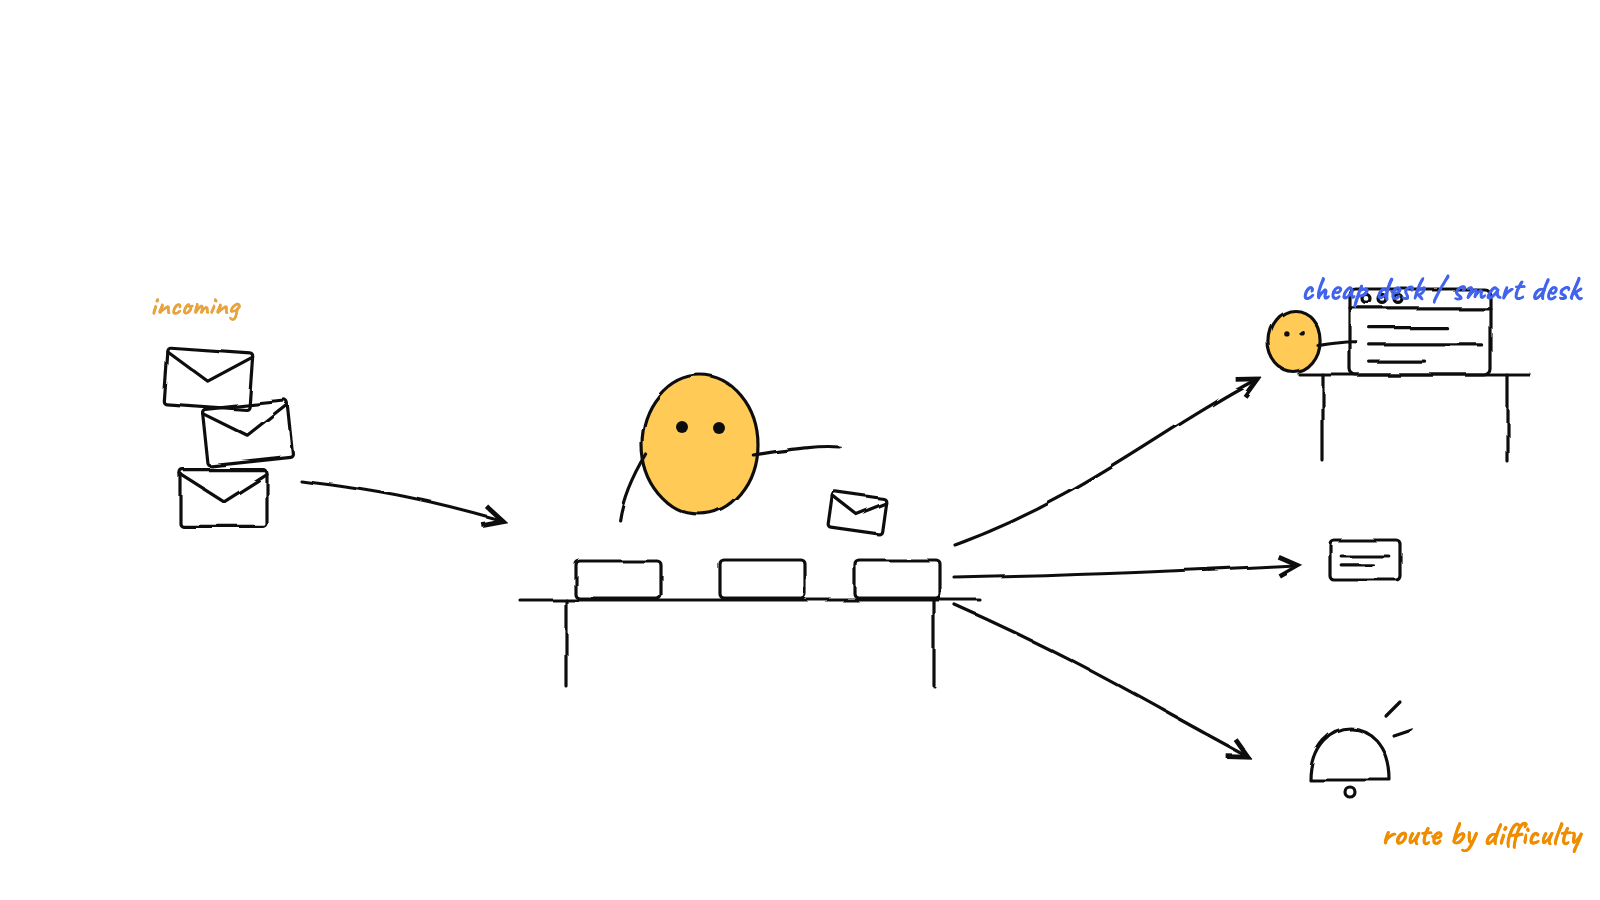
Why a hive of agents shouldn't all run the biggest model — and how routing the right task to the right model cuts cost and latency without losing quality.
An agent re-sends the same prompt, tools, and context every turn. Prompt caching makes you pay for that prefix once — here's how to design for it.